← All projects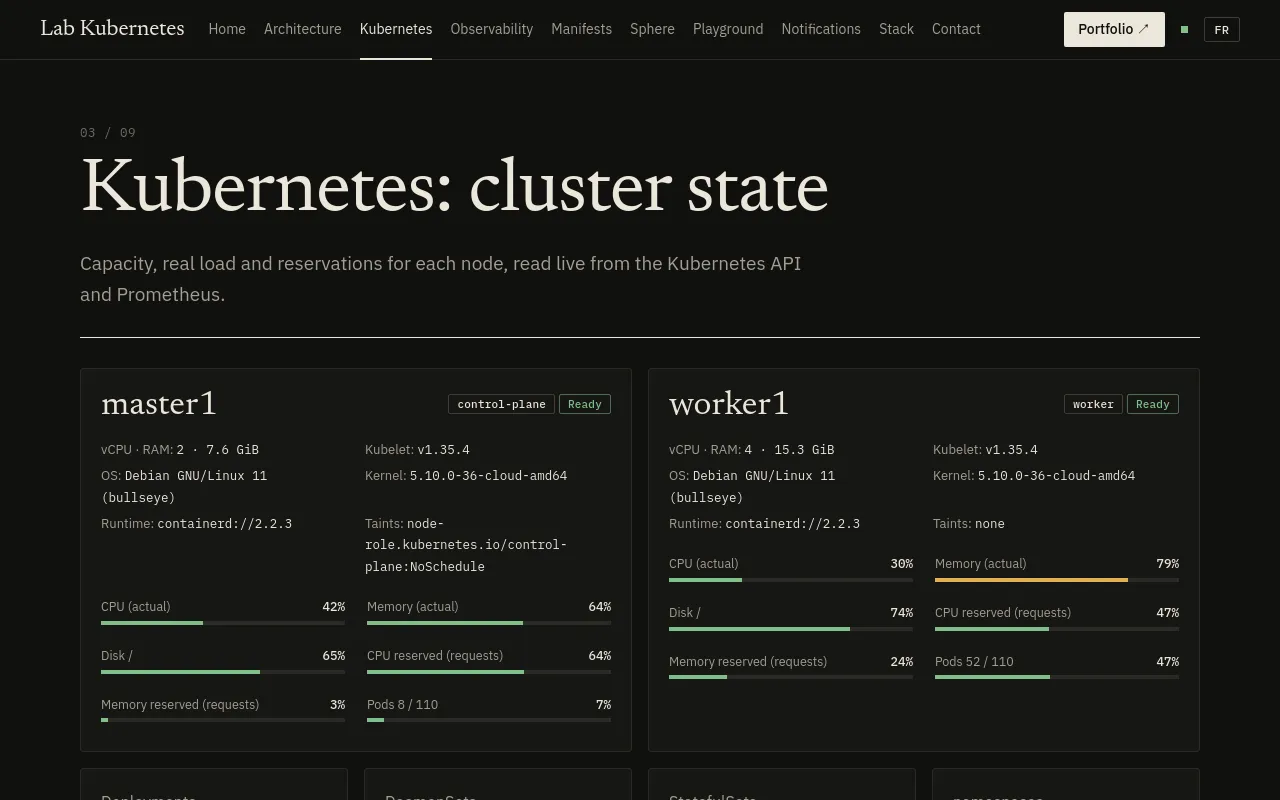
Platform · Kubernetes
A Kubernetes cluster built and run on my own
Two machines, Kubernetes installed with Kubespray, and everything needed to host public sites: HTTPS entry point, automatic certificates, Git forge, monitoring, verified backups.
- Kubespray
- Calico
- ingress-nginx
- cert-manager
- Helm
- kube-prometheus-stack
- GitLab
- Zabbix
The problem
Keeping my Kubernetes skills sharp outside a company, on real infrastructure exposed to the Internet rather than on a laptop, with what comes with it: security, certificates, backups, monitoring.
What I built
- Kubernetes installed with Kubespray: one control plane and one worker, Calico networking; metrics-server, local-path storage and cert-manager as add-ons.
- ingress-nginx on the worker's ports 80 and 443: a single entry point, a Let's Encrypt certificate for every name, issued and renewed by cert-manager.
- GitLab (forge, CI, image registry) and Zabbix installed on the machine, published behind the ingress through selector-less Services: their ports cannot be reached from the Internet.
- Prometheus, Alertmanager and Grafana (kube-prometheus-stack) installed with Helm, values files under version control.
- Nightly backups of etcd and its PKI, GitLab and Zabbix, each machine keeping the other's, seven copies of each.
Choices and reasons
- A firewall on the worker's public interface: only SSH, HTTP, HTTPS, the VPN and the other node get through. The kubelet and the exporters no longer answer the Internet.
- Pod Security "restricted" on application namespaces, and no Kubernetes token in pods that do not need one.
- Alerts are mailed straight to the domain's mail server, with no SMTP account or password; an alert fires after 30 hours without a successful backup.
Checked
- etcd snapshot restored into a throwaway directory (1,804 keys), full GitLab archive read back (database and 43 repositories), Zabbix dump readable (186 tables).
- The cluster's state is public and live on lab.hoortrend.com: nodes, pods, alerts, and a sandbox anyone can break.
Limits and next steps
One control plane and one worker: no high availability, a deliberate choice for a lab. Backups stay with the same hosting provider, and a full restore has not been timed yet. Next step: an automated, measured recovery drill.